


An in-house generative AI study group will not become part of daily work simply because it demonstrates useful prompts. It needs to connect real tasks, acceptable-use rules, data protection, evaluation, and improvement in one operating loop. This guide is for teams in Thailand and Southeast Asia that want to design and run a 30-day pilot, then decide whether outside training or adoption support is needed.
The OECD reports that around 40% of employers in manufacturing and finance that have not adopted AI identify skills as the main barrier. More than half of SMEs not yet using generative AI also report a skills barrier. It also says users who receive training are more likely to report positive outcomes such as better performance and working conditions. An internal study group is therefore not a side event; it is part of the adoption process that turns access to a tool into safe business capability.
A separate 2025 OECD report found that 23.6% of SMEs using generative AI said their employees participated in AI-related training, ranging from 11.3% in Japan to 29.4% in Canada. These are country-level survey figures, not participation targets for an individual company; they are better used as context showing that continuous learning is not yet routine.
Do not make attendance the goal of an in-house generative AI study group
Start with the work to be improved, not the number of employees who log in. “Everyone should use AI” is too broad. A useful objective is specific: reduce the effort needed to structure actions after a sales meeting, assist with summarising maintenance records, or create a first draft of an internal document in Japanese, English, or Thai. For each case, identify the task, permitted inputs, output owner, and human approver.
The ILO’s 2025 update finds that one in four workers worldwide are in occupations with some degree of GenAI exposure. Because many tasks still require human input, transformation is more likely than replacement. Training should therefore teach both where AI can assist and where human judgement must remain.
Define the objective at three levels
| Level | Question | Deliverable |
|---|---|---|
| Work | Which repeated task or preparation for judgement should improve? | Use-case list, current workflow, expected output |
| Capability | What should employees be able to do independently? | Competency definitions, exercises, rubric |
| Control | What must not be entered, and who approves exceptions? | Use policy, data classification, stop-and-escalate path |
All three levels are necessary. A work-only programme can create data risk. A policy-only session may discourage all use. A prompt-only class provides no way to measure business value. Together, they turn the study group into a governed improvement experiment.
Classify the programme as Adopter, Customizer, or Maker
ETDA’s organisational guidance describes three ways of applying generative AI: an Adopter uses an off-the-shelf service; a Customizer configures a model or solution for an organisation-specific purpose, including approaches such as retrieval-augmented generation; and a Maker develops a foundation model. Each requires different learning content and controls.
| Application model | Main learning focus | First control to establish |
|---|---|---|
| Adopter | Approved tools, prompting, output review | Accounts, prohibited inputs, sharing scope |
| Customizer | Knowledge sources, access, citations, evaluation set | Data connections, authorisation, update ownership |
| Maker | Model and data design, evaluation, monitoring | Development responsibility, change control, stop criteria |
A 30-day company programme will usually begin with the Adopter model. If Customizer or Maker work is in scope, separate general-user sessions from developer and administrator training. Teaching model engineering to ordinary chat users does not solve their workflow problem, while teaching only prohibited inputs to a RAG team leaves access control and evaluation unanswered.
Assign clear roles for corporate AI education
Putting the entire programme on one “AI champion” creates gaps. Business, technology, information management, learning, and executive decisions all meet in this programme. One person may hold several roles in a small organisation, but the responsibilities should still be named.
| Role | Core responsibility | What remains after 30 days |
|---|---|---|
| Sponsor | Scope, risk tolerance, continuation decision | Priority and scale/stop decision |
| Programme owner | Schedule, participants, material, issue log | Operating record and next cycle |
| Process owner | Current method, acceptance criteria, review | Approved use case and open issues |
| IT/security | Tool, account, logging, connectivity | Approved environment and constraints |
| Legal/compliance | Contract, privacy, IP, policy | Use conditions and exception route |
| Facilitator | Explanation, practice, questions, psychological safety | FAQ and material revisions |
| Participant | Practice, checks, incident reporting | Work sample, reflection, improvement proposal |
If you create a RACI chart, include at least tool approval, material approval, real-data use, external-document use, incident response, and continuation decisions. Its purpose is to remove the assumption that somebody else will review a risk.
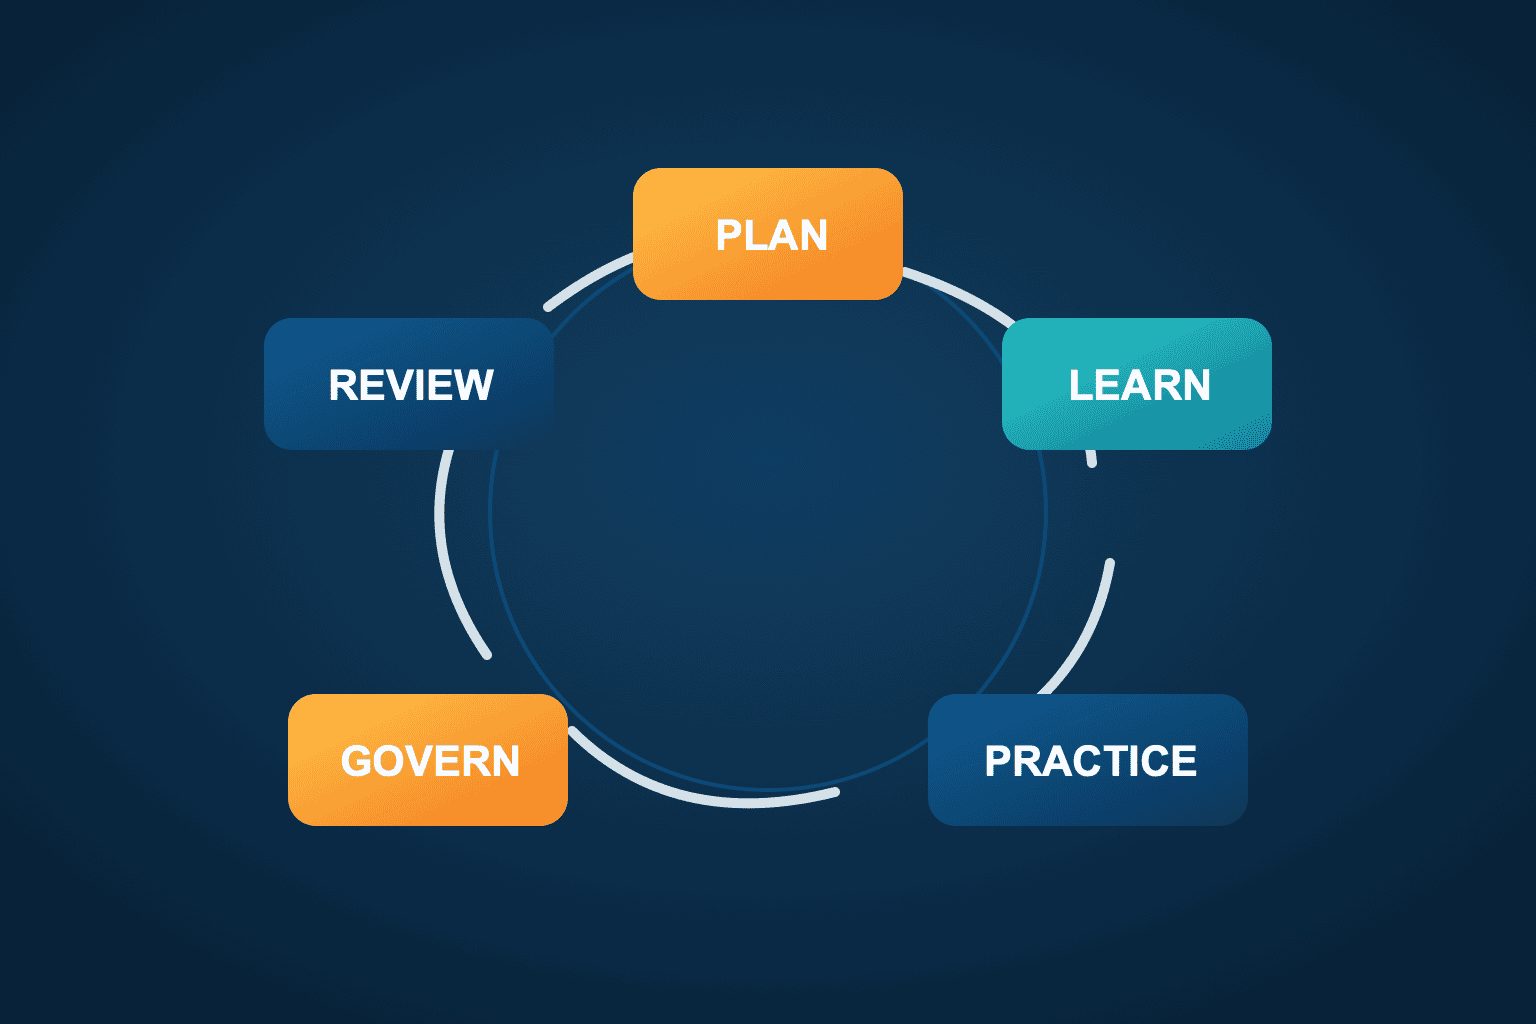
A 30-day plan for making generative AI useful at work
The following is a design example, not a statutory or standards-based timeline. Adjust it to the size of the organisation, existing controls, approval speed, and task risk.
Days 1–3: Align the purpose, target work, and prohibitions
The sponsor and process owners select two or three use cases. Do not ask only whether employees want to use AI. Ask which documents repeat every week, what delays judgement, and what data classes appear in the task. In parallel, issue a one-page note covering approved tools, account access, prohibited data, output use, and the help channel.
Good first use cases have errors that a knowledgeable reviewer can detect, limited consequences when a trial fails, and a measurable current process. Legal decisions, employment evaluation, pricing decisions, safety control, and medical decisions should not be casual workshop exercises. Route high-impact uses through specialist review as separate projects.
Days 4–7: Build shared foundations for risk and verification
Explain that a generative model produces likely outputs and that a fluent answer may still be wrong. Participants should understand that data may be transmitted to an external service and that contractual and configuration details affect handling. Teach three pauses: before input, after output, and before sharing.
Use public or synthetic information in exercises. Do not turn the session into a competition for the most impressive output. Ask learners to find unsupported claims, omissions, bias, ambiguity, and unsafe instructions. Keep failed examples and the reason they were corrected as part of the material.
Days 8–14: Run department-specific use-case labs
Create small groups for sales, purchasing, manufacturing, quality, HR, or other functions. For one use case, document the current process, the information supplied to AI, the expected format, the human review, the storage location, and the condition for not using AI. Treat the prompt as a controlled step in a workflow rather than a standalone sentence.
Participants should use a shared evaluation set more than once. This checks repeatability instead of celebrating a lucky result. For multilingual documents, assess meaning, proper nouns, units, dates, honorifics, and company terminology separately. For manufacturing records, focus on quantities, equipment IDs, lot information, and exception categories.
Days 15–21: Connect learning to the use policy and standard work
Convert questions from the pilot into practical rules. “Do not enter confidential information” is not enough. Define what confidential means, whether anonymisation is sufficient, what an approved environment can handle, where generated work is saved, and whom to contact after an unintended disclosure.
Standard work should state whether AI use must be disclosed, who reviews the output, what evidence is retained, how revisions are recorded, and who carries final accountability. Responsibility does not move to the model. An approver of an external communication or business decision needs access to both the content and its supporting sources.
Days 22–27: Pilot approved work and provide coaching
Use only the approved, limited use cases. A facilitator should observe inputs, the amount of correction, missed checks, and decisions to stop—not merely answer tool questions. When a participant struggles, classify the problem as material, configuration, policy, process, or skill rather than labelling the employee as incapable.
Results such as “the manual method was faster,” “the evidence could not be verified,” or “anonymisation required too much effort” are valuable. A documented decision not to adopt a use case is a sign of mature AI capability.
Days 28–30: Evaluate and decide what happens next
The closing review should not be a theatre of impressive demos. For each use case, report the baseline, trial conditions, measured result, identified risks, open issues, and continuation conditions. The sponsor selects full scale-up, limited continuation, further testing, or stop, then records the reason and the next owner.
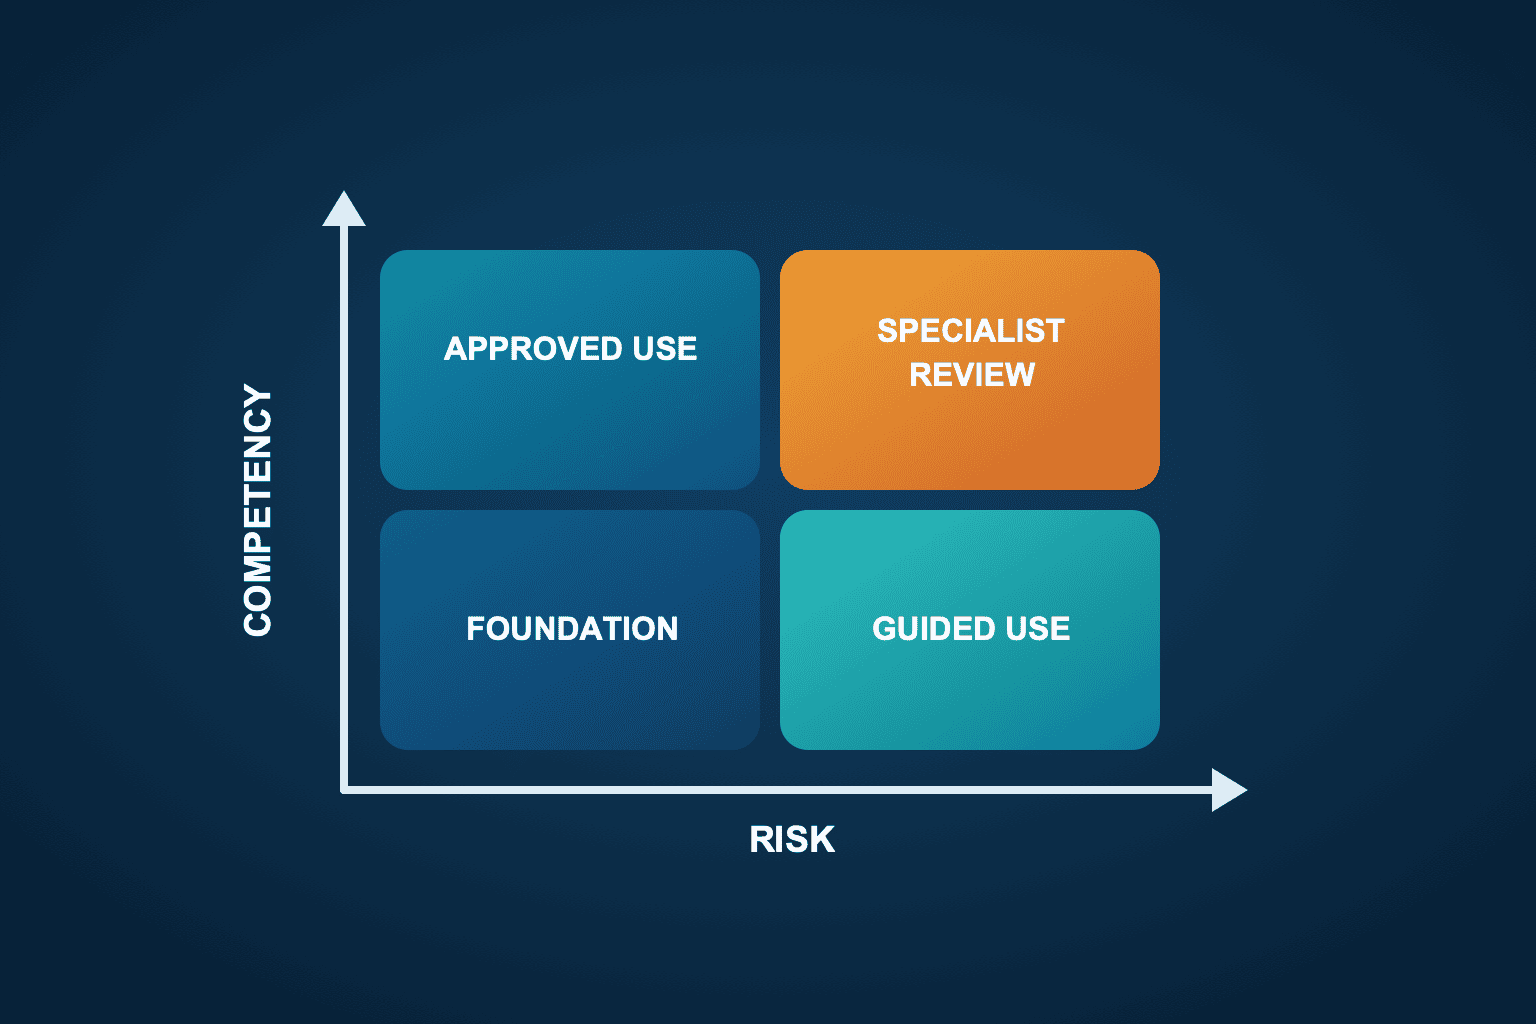
Design training material in four layers
A sequence of short explanations, practice, and reflection connects to work more effectively than one long lecture. Build the material in four layers:
- Knowledge: capabilities and limits, data handling, IP, privacy, and bias.
- Operation: approved sign-in, history, sharing, deletion, and output formatting.
- Judgement: cases that require deciding whether a task, input, or output is acceptable and who reviews it.
- Work: an end-to-end exercise using a real workflow structure, a baseline, quality review, and a record.
Do not distribute a “perfect prompt library”
Templates are useful, but a prompt without context becomes a false promise. Attach a task, permitted inputs, prohibited inputs, expected output, review checklist, non-use condition, owner, and revision date to every template. Models and services change, so version the material and set a re-evaluation point.
Localise for a Thai workplace
A Japanese-led company in Thailand may agree policy in Japanese, coordinate in English, and communicate with employees in Thai. Translation exercises should check the force of mandatory language, responsibility, units, names, and prohibited wording—not just fluency. Provide a channel where participants can ask questions in their strongest language and maintain a controlled glossary.
Make prohibited data and anonymisation part of the exercise
Data protection will not become behaviour after one slide. Participants must practise classifying information before opening the input field. The table below is a design example and must be aligned with the company’s legal and security requirements.
| Data class | Treatment in a general workshop | Example |
|---|---|---|
| Public | May be used in an approved environment | Published product information, government material |
| Internal | Prefer synthetic or abstracted content; approve the purpose | Internal procedures, unpublished meeting notes |
| Confidential | Prohibit; review separately even in dedicated tools | Customer drawings, prices, contracts, source code |
| Personal | Prohibit or apply strict approval and minimisation | Names, contacts, performance, health information |
Removing a name is not sufficient anonymisation
Changing a customer to “Company A” may not prevent re-identification when a project name, date, site, product model, value, and writing style remain. Teach participants to distinguish direct identifiers, indirect identifiers, business secrets, and contractual confidentiality. If useful meaning cannot be retained safely, build synthetic data that reproduces only the structure.
Controls should also cover attachments, screenshots, browser extensions, shared-conversation links, and synchronised history. When in doubt, the expected action is to stop the input and ask, not to experiment first and report later.
Write a short policy with maintainable operating schedules
A long policy read once will not guide work. Keep principles and accountability in the main document, and place rapidly changing details—approved tools, allowed uses, data classes, and contacts—in maintained schedules. At minimum, cover:
- covered people and tools;
- allowed, prohibited, and high-impact uses;
- prohibited data and anonymisation conditions;
- factual, IP, citation, and bias checks;
- external sharing and approval;
- accounts, logging, retention, and deletion;
- incident reporting, suspension, and exceptions; and
- re-evaluation after material, tool, or model changes.
The NIST Generative AI Profile helps organisations identify GenAI-specific risks and choose risk-management actions aligned with their goals and priorities. ISO/IEC 42001 specifies requirements for establishing, implementing, maintaining, and continually improving an AI management system. A 30-day programme does not imply conformity or certification, but both references support the idea that training, policy, responsibility, monitoring, and improvement must connect.
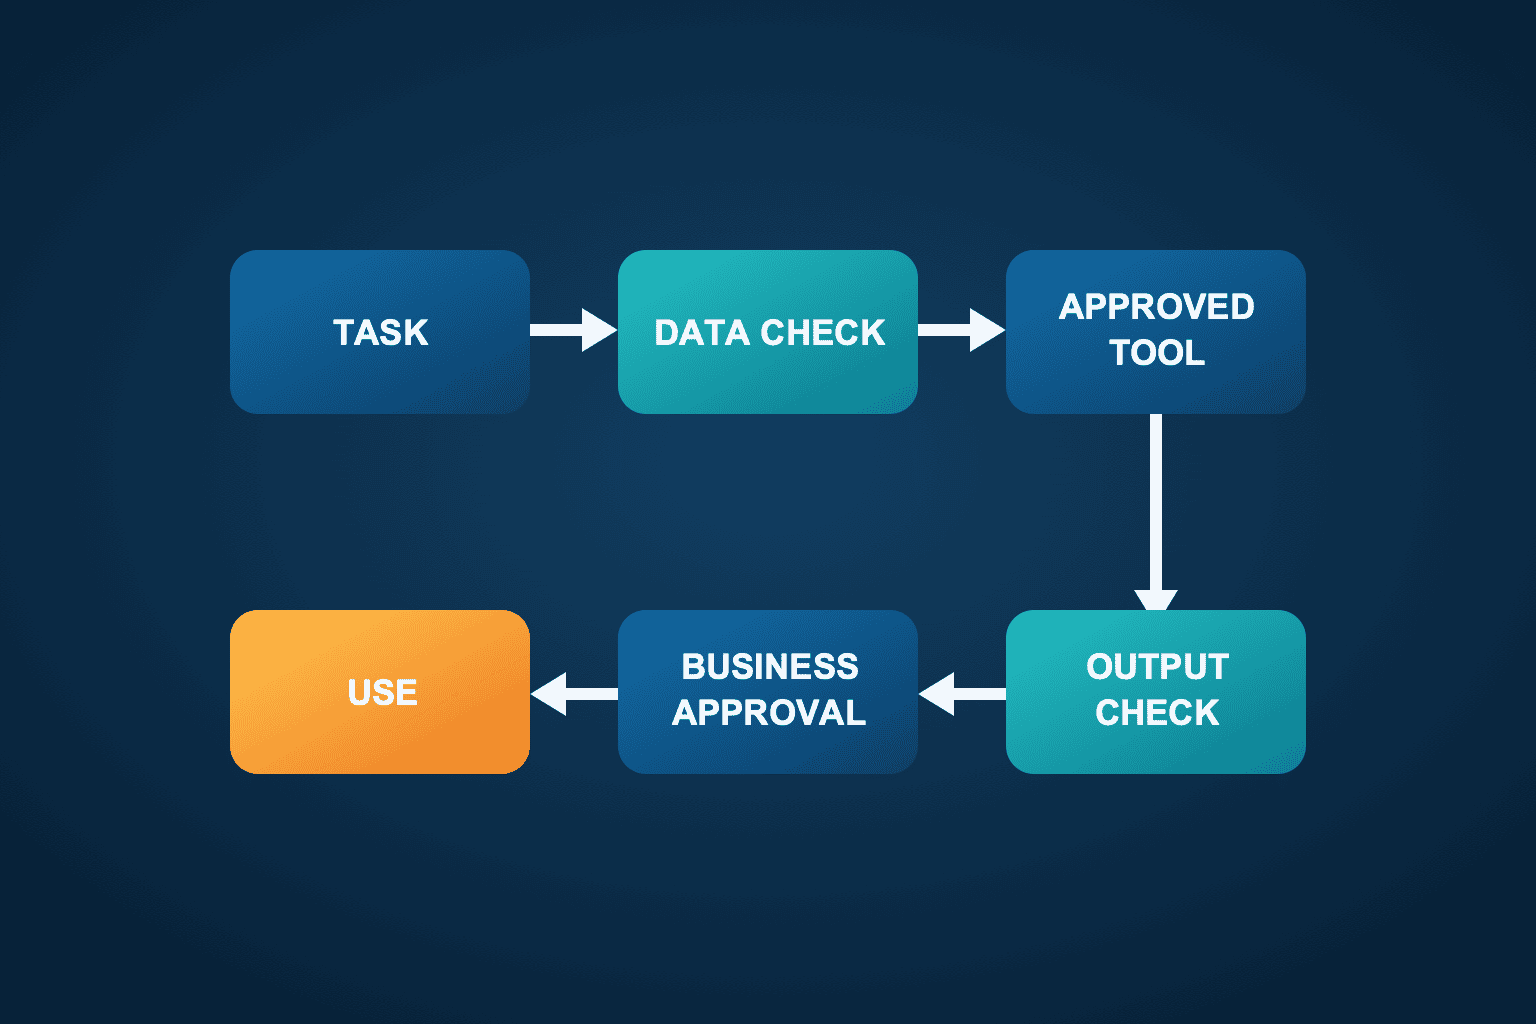
Use one matrix for competence and risk
Fast operation does not equal safe operation. Evaluate whether participants can produce useful work and whether they can stop unsafe work.
| Competency | Foundation behaviour | Behaviour before operational approval |
|---|---|---|
| Problem framing | Explains the purpose and expected format | Compares AI with a non-AI option |
| Input control | Identifies prohibited data | Checks re-identification after anonymisation |
| Output evaluation | Finds obvious errors | Verifies evidence, omissions, bias, and repeatability |
| Workflow integration | Saves work in the right place | Completes approval, record, and exception handling |
| Incident response | Stops and asks for help | Limits impact, records, and reports |
Evaluate behaviour, not only knowledge
Combine a short pre/post check with case exercises, work-sample review, observation, and brief interviews. A learner who passes a quiz but enters real confidential data is not ready for operational use. A learner with a basic prompt who frames the task, classifies data, verifies the result, and stops when necessary has a sound foundation.
KPI formulas can include the following. They are design examples; set targets only after measuring the baseline.
- Exercise completion rate = completers ÷ target participants
- Safe-behaviour rate = exercises with all mandatory checks ÷ evaluated exercises
- Operational adoption rate = approved use cases retained ÷ use cases trialled
- Rework rate = heavily revised or rebuilt outputs ÷ AI-assisted outputs
- Incident reporting time = time of report minus time of discovery
If time saving is the only KPI, employees may be rewarded for skipping verification. Review quality, risk, and employee experience alongside end-to-end elapsed time.
Operate weekly so AI use can become sustainable
Use often fades after the first month because there is no help channel, material becomes outdated, and experience is not shared. Keep a lightweight operating rhythm:
- a weekly clinic that prioritises problems over success stories;
- a use-case register with owner, data class, approval, and review date;
- version control for prompts and procedures, including reasons for changes;
- a monthly review of use, quality, incidents, stopped cases, and next priorities; and
- a quarterly check of policies, tools, contracts, settings, and model changes.
ETDA’s 2026 Trust AI direction highlights AI literacy, safe use, and ethical impact assessment. Sustainable adoption depends on creating a culture in which doubts and early warning signs can be raised quickly, not simply on increasing usage.
Common failure patterns and corrections
Failure 1: The programme ends with a product tour
Employees understand features but cannot place them in a workflow. Start with the input, judgement, and output of current work, then select where the tool may assist.
Failure 2: The most technical employee becomes the sole authority
Technical expertise does not settle process, legal, or information-management questions. Include process owners, IT, and legal/compliance in material approval.
Failure 3: Real data is used before any rule exists
It is correct to improve the policy with operational learning, but initial prohibitions and an approved environment must exist first. Begin with public and synthetic material.
Failure 4: Only success stories are shared
If reasons for rejection disappear, another team repeats the same experiment. Record stopped and non-adopted cases with their criteria.
Failure 5: Drafting speed is the only outcome
A faster draft does not help if review and correction increase. Measure the whole path from start to approval, correction effort, quality, and risk events.
Failure 6: Everyone receives identical material
Executives, general users, developers, and administrators carry different decisions. Share foundations, then split into role-specific practice.
Failure 7: A certificate is treated as adoption
Immediate comprehension and later behaviour are different. Follow approved use cases, help requests, work reviews, and re-evaluation.
How to choose an external training or adoption partner
Outside support can help when the company lacks time for material design, facilitation, security review, or multilingual delivery. Do not select a provider only by speaker reputation, prompt count, or satisfaction score. Use an RFP to test whether the provider can connect learning to your work and controls. For a focused procurement checklist, see how to select a generative AI training provider in Thailand.
Requirements to include in the RFP
| Topic | What to confirm | Evidence to request |
|---|---|---|
| Work relevance | Material connects to company workflows | Discovery method and sample questionnaire |
| Safety | Prohibited data, anonymisation, incidents | Exercise and facilitator procedures |
| Languages | Meaning is consistent in required languages | Sample material and terminology control |
| Evaluation | Results go beyond satisfaction | Rubric and work-review example |
| Adoption | Questions and improvement continue after class | Coaching, register, review proposal |
| Data | Provider handling of files and logs | Location, retention, deletion, subcontractors |
| IP | Rights to material, outputs, and prompts | Licence, reuse scope, editable deliverables |
| Exit | Internal operation after the engagement | Handover and train-the-trainer plan |
Use a scenario-based demonstration
Ask providers to run a short session using a synthetic case close to your business. Observe whether the facilitator stops prohibited data, challenges a plausible but incorrect output, supports beginners, and avoids rewriting company terminology without permission.
Compare total cost, not only tuition. Include discovery, material development, translation, accounts, environment setup, post-training coaching, rights to deliverables, and later revisions. If a budget example is needed, show unit price and quantity and state tax, currency, travel, and tool assumptions. This article does not estimate market rates.
Keep accountable decisions inside the company
The provider cannot own your business priorities, data classification, final approval, or incident response. Outside support adds expertise and operating capacity; it does not transfer accountability. Define provider tasks and company approvals before contracting.
If the need extends to use-case selection, governance, technical integration, and coaching, review the practical guide to AI adoption support in Thailand.
Checklist for the day-30 decision
- Target and excluded work are documented.
- Approved tools and account owners are identified.
- Prohibited data, anonymisation, and exceptions are understood.
- Output reviewers and evidence exist.
- Multilingual and technical-term quality checks exist.
- Incident and suspension routes work.
- Every use case has an owner and review date.
- KPIs cover time, quality, risk, and experience.
- Material and policy owners are named.
- The exit from external support is defined.
If a material gap remains, continue with a limited scope rather than rushing to company-wide access. Scale when operating responsibility and verification capability have increased, not when attendance has increased.
FAQ about corporate AI education and adoption
What is required to start an in-house generative AI study group?
Define target work, sponsor, process owner, approved tool, prohibited data, output review, and help channel. Use public or synthetic data first and approve real-data use separately.
Should corporate AI education cover every employee at once?
A shared foundation can be broad, but operational practice should be separated by role and data risk. Pilot with work that has limited consequences and measurable quality, improve the material, and then expand.
Should AI talent development focus on prompting?
Prompting is one component. Equally assess problem framing, data classification, output verification, workflow approval, and incident reporting. These judgement skills remain useful when models and interfaces change.
How should generative AI productivity be measured?
Compare end-to-end time from work start to approval, correction effort, quality, errors, and review burden under equivalent conditions. Record the trial conditions and human checks.
What does AI adoption support do after training?
It maintains a clinic, use-case register, work reviews, material versions, and policy checks. It also records uses that were stopped and the reason.
Can employees bring real company data to exercises?
Not by default. Anonymised information may still be identifiable or contractually restricted. Confirm classification, contracts, law, tool settings, necessity, and minimum scope before approval.
How should an external training company be selected?
Compare work relevance, safety, language delivery, evaluation, follow-up, data handling, IP, and handover through an RFP. Verify delivery with a scenario and sample outputs.
Conclusion: Treat the study group as a small management system
The key to an effective in-house generative AI study group is not an entertaining lecture. It is a loop that begins with a defined task and continues through data classification, output verification, approval, incident response, and improvement. The 30 days create a safe learning foundation—including the ability to decide not to use AI—rather than a finished transformation.
TOMAS TECH can support the planning of an internal GenAI programme for teams in Thailand, including material, acceptable-use rules, department exercises, evaluation, and post-training coaching. You are welcome to contact us while the programme is still at the planning stage, including for a design review of an internally led approach.
References
- OECD, AI and skills: https://www.oecd.org/en/publications/ai-and-skills_f843b352-en/full-report.html
- OECD, Generative AI and the SME Workforce: https://www.oecd.org/en/publications/generative-ai-and-the-sme-workforce_2d08b99d-en/full-report/component-6.html
- ILO, Generative AI and jobs: A 2025 update: https://www.ilo.org/publications/generative-ai-and-jobs-2025-update
- ETDA, Generative AI Governance Guideline for Organizations: https://www.etda.or.th/getattachment/6050a4b7-defd-4dba-8cbc-ff6a444a3d08/20240910_GenerativeAIGovernanceGuideline_Vol1_AIGC.pdf.aspx
- ETDA, Driving Trust AI Governance 2026: https://www.etda.or.th/th/pr-news/aigc_Driving-Trust_AI_Governance.aspx
- NIST, AI Risk Management Framework and Generative AI Profile: https://www.nist.gov/itl/ai-risk-management-framework
- ISO, ISO/IEC 42001 AI management systems: https://www.iso.org/standard/42001


